Product
Every enterprise AI request runs through one governed path.
An OpenAI-compatible gateway, self-hosted inside your own network — one base-URL change, ten layers of governance on every request.
The problem
AI arrived one tool at a time. Nothing controls the execution path.
01 · Visibility
“What AI exists?”
Which models, agents, and vendor solutions are touching enterprise or customer data?
02 · Governance
“Who can use what?”
Which models, agents, and tools are approved for which workloads?
03 · Assurance
“Can we trust it?”
Was the model or agent evaluated before deployment — and does it remain safe after changes?
04 · Runtime control
“What happens when AI acts?”
Can we enforce policy, restrict access, or stop a misbehaving agent without halting the workflow?
05 · Economics
“What is AI costing us?”
Which teams, applications, and models are driving usage and cost?
06 · Accountability
“Can we prove what happened?”
Who used which model, with which policy, and what happened at execution time?
Six questions, one cause: AI executes without a unified control layer.
Unified control layer across models, agents, tools & data
Enterprise AI
Customer-facing AI · Internal AI · Agents · AI-enabled workflows · Vendor AI
↓
Ordinis Control Plane
All ten layers structurally built — enterprise-grade hardening targeted for Q4 2026
Govern — every model, every routing decision
Protect — every prompt, every response
Empower — your infrastructure, your rules
↓
AI Ecosystem
OpenAI · Anthropic · Gemini · Open-source · Private models · MCP · APIs · Enterprise tools · Databases · External services
Deploys into your existing AI stack
- One base-URL change per application.
- Existing SDKs and tools work unchanged.
- Every control runs inside your perimeter. Prompts stay there too.
How it works — a prompt's path through Ordinis
Your App
Same OpenAI-format SDK, one line changed: the base URL
Ordinis Gateway
Govern the model, protect the prompt — inside your VPC
Model Provider
On-prem, OpenAI, Anthropic, or any configured upstream
Reroute
Sensitive request → your own on-prem model. Nothing external.
Redact
PII swapped for reversible tokens before the call leaves.
Block
Policy violation stopped outright — request or response.
Three views of the same core engine
Every request passes through the core engine first: auth, DLP scan, and routing decision — before it ever reaches a regulator plugin or a model provider.
In practice
What the control plane does at runtime.
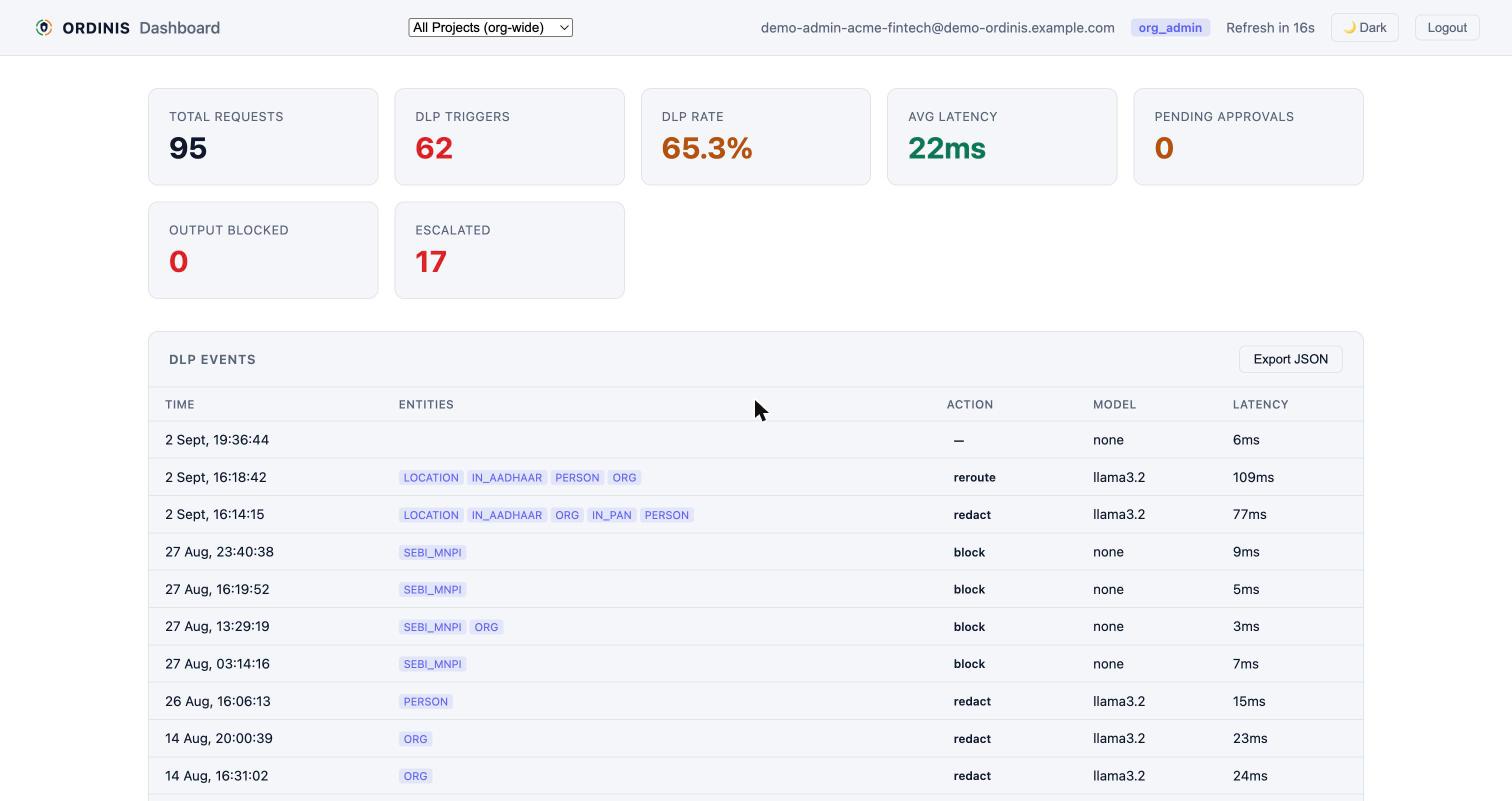
DLP event log — redact, reroute, and block actions, Ordinis demo tenant
DLP & Redaction
Sensitive data never leaves the perimeter.
When a prompt contains a regulated data type — an Aadhaar number, a card PAN, an account number — Ordinis detects it and reroutes, redacts, or blocks the request before it reaches the model, depending on policy.
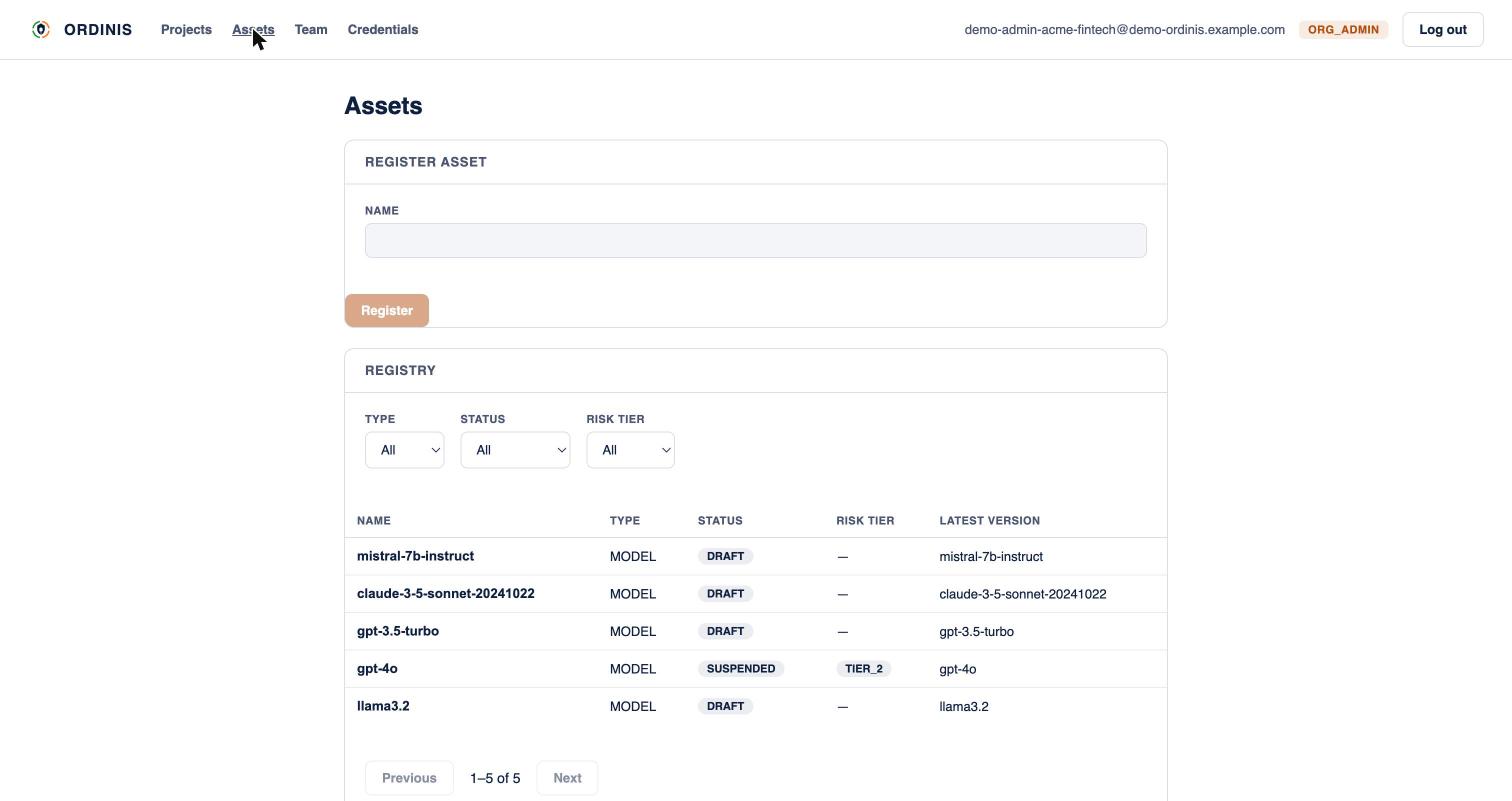
AI asset registry, Ordinis demo tenant
AI Asset Registry
Every model your enterprise uses, in one register.
Each model is registered, versioned, and risk-tiered — draft, active, or suspended — so a model that fails review can be pulled from service without a code change, and concentration risk is visible before it's a finding.
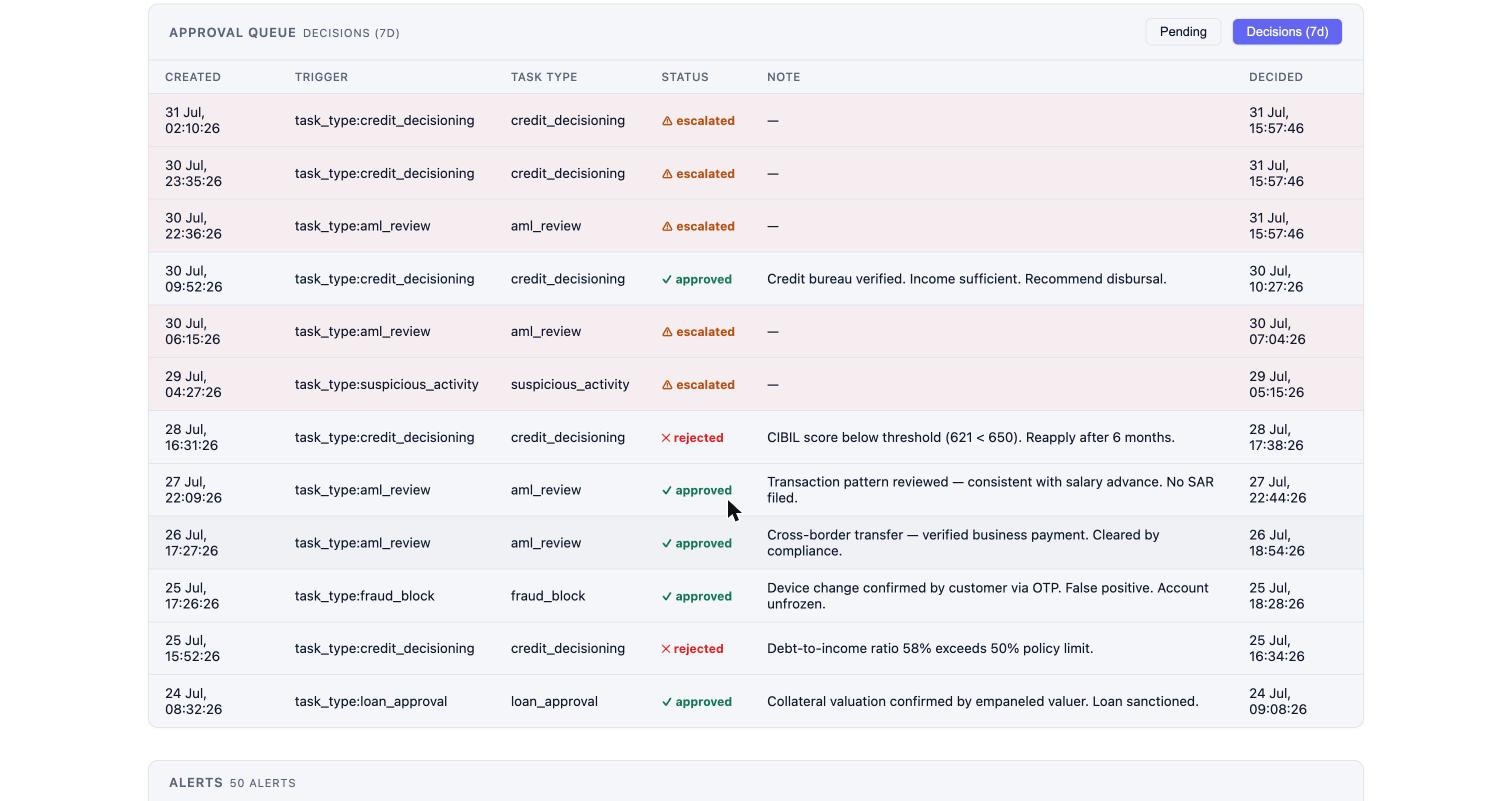
Approval decisions, Ordinis demo tenant
Human Oversight & Approval Queue
A person stays in the loop on what matters.
High-risk outputs pause for human review instead of executing automatically — with real pause, resume, and re-execution, not just a log entry after the fact.
Govern — every model, every request
Identity & access
SSO via OIDC and per-key token budgets gate every request before it's routed.
Risk-tiered registry
Every model scored by materiality, complexity, and autonomy — the risk tier travels with every routing decision.
Kill switch
Suspend a model instantly — suspended models are filtered out of live routing, not just flagged.
Validation gating
New models register as DRAFT and are blocked from serving traffic until marked VALIDATED.
Policy-as-code
Policy changes hot-reload across every application instantly, without redeploying apps.
Prompt injection defense
Every request scored for injection risk in real time, before it ever reaches a model.
Multi-provider routing
Circuit breakers and rate limits per upstream, with automatic failover across providers.
Model integrity monitoring
Detects weight changes and silent version upgrades on pinned models — a provider swap never happens unnoticed.
Anomaly detection
Session-level volume, DLP, and error-surge spikes flagged automatically, not just per-request checks.
Protect — every prompt, every response
Data loss prevention
Reroutes, tokenises, minimises, or blocks — 12 entity types incl. PAN/Aadhaar/IFSC/UPI, plus multimodal DLP for images and files.
Human oversight & approval queues
Redact or block sensitive output, with human-in-the-loop approval — real pause, resume, and re-execution.
Tamper-evident audit
SHA-256 hash-chained log of every request — the report an examiner can be handed directly.
Compliance reporting
72-hour examiner access via a dedicated regulatory examination portal.
Empower — your infrastructure, your rules
Self-hosted, always
Docker or Helm, inside your VPC. Not SaaS — we never see a prompt.
One-line integration
OpenAI-compatible API. Change the base URL; your SDKs stay identical.
Pilot in 2-4 weeks
Deploy against one project, one team, see the audit trail before you commit.